Data Engineering
Scalable ETL/ELT pipelines, data architecture, distributed processing and reliable data workflows.
I design scalable data platforms, real-time processing pipelines and modern lakehouse architectures using Spark, Kafka, Hadoop and cloud technologies. My professional journey spans 14+ years , including 7+ years in Data Engineering , with teaching experience since September 2022.
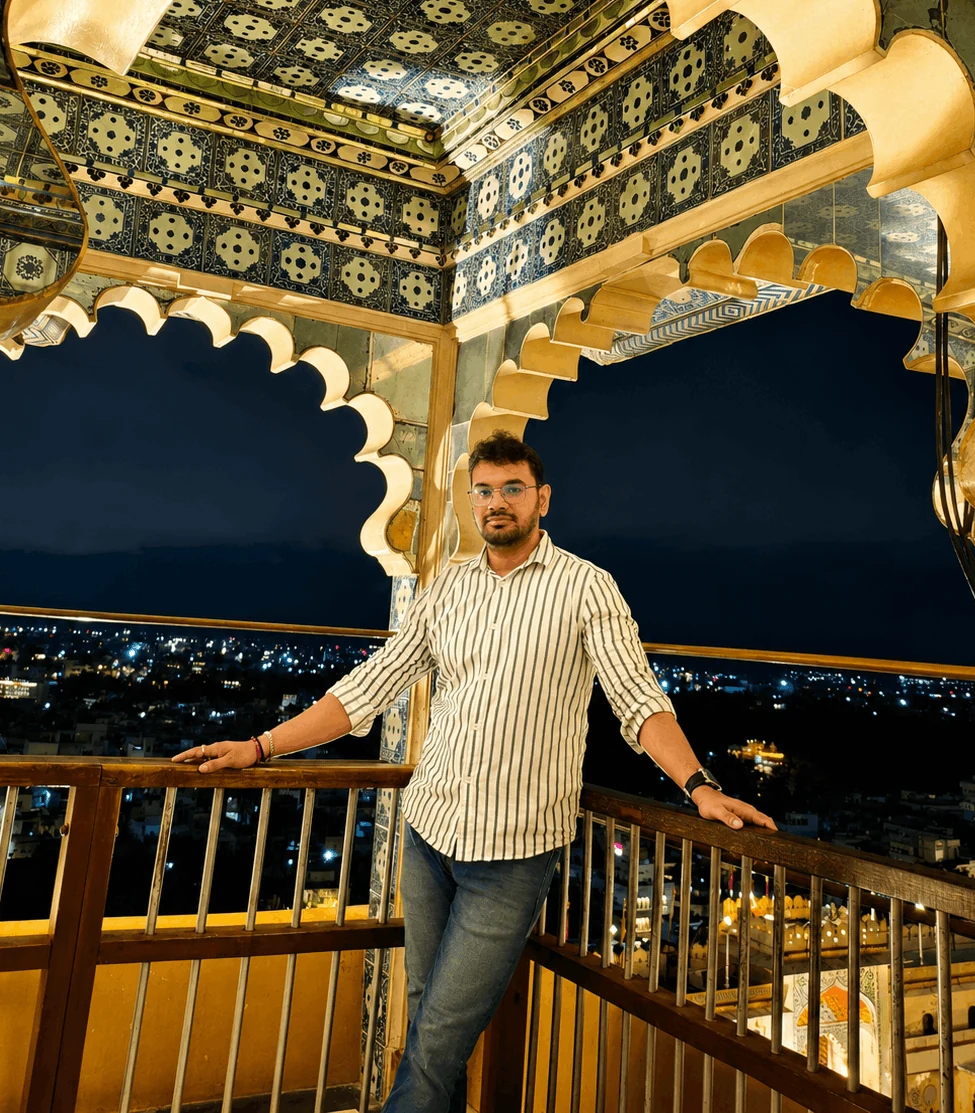
Turning data into knowledge and knowledge into impact.
My background combines technology, infrastructure, networking and software systems with a long-term specialization in Data Engineering. I work across scalable pipelines, distributed data platforms, real-time processing, cloud environments and technical education.
Scalable ETL/ELT pipelines, data architecture, distributed processing and reliable data workflows.
Spark, Hadoop, Kafka, lakehouse technologies, AWS, EMR, S3 and high-volume data systems.
Networking, routing and switching, TCP/IP, Linux, server environments and infrastructure fundamentals.
Practical technical education, mentoring and applied research in modern data systems.
Professional focus on Data Engineering, distributed processing, real-time systems, cloud data platforms, data pipelines and large-scale workloads.
Teaching Big Data, Data Engineering, Spark, Hadoop, programming, analytics and practical data systems concepts.
Professional foundation across technology, networking, routing and switching, server environments and software/IT systems.
Kafka and Spark Structured Streaming pipeline for scalable ingestion and real-time processing.
Performance comparison of Delta Lake, Apache Iceberg and Apache Hudi across S3 and HDFS.
Automated workflows for scheduling, monitoring and repeatable data pipeline execution.
Distributed processing workflows for high-volume datasets with performance and reliability considerations.
Research focuses on the real-time performance comparison of modern data lakehouse technologies using Kafka and Spark Structured Streaming, with emphasis on storage systems, query performance and scalable data processing.
Teaching experience since September 2022, combining theory with hands-on examples, architecture thinking and real-world data engineering problems.
A multidisciplinary academic profile combining data science, information technology, business and doctoral research.
IIC University of Technology (IICUT)
Doctoral research · field to be specifiedLiverpool John Moores University
Data Science, analytics and applied researchAmity University
Business, management and information technologyIIIT Bangalore
Professional program in Data Science and analyticsRouting, Switching & Networking
Microsoft Certified Technology Specialist
Data Engineering & ML
AI Certification
Oracle technologies & systems
Big Data technologies
Software engineering
Vipin Singh Negi is a Big Data Engineer, Educator and Researcher with 14+ years of professional experience, including 7+ years in Data Engineering and teaching experience since September 2022.
Big Data Engineering, Apache Spark, Hadoop, Kafka, data lakehouse technologies, real-time processing, AWS, networking, routing and switching, Linux and server infrastructure.
His research focuses on the real-time performance comparison of Delta Lake, Apache Iceberg and Apache Hudi using Kafka and Spark Structured Streaming.
Deep-dives on distributed streaming, Spark performance and Lakehouse architecture.
2026 benchmark covering metadata, writes, compaction and query latency.
Read guide →
Production migration, resilience and exactly-once streaming patterns.
Read guide →
Eliminating shuffles and skew with AQE, joins and executor tuning.
Read guide →
Latency, state, checkpointing and real-time pipeline architecture.
Read guide →For data engineering, research, teaching, mentoring or professional collaboration.